
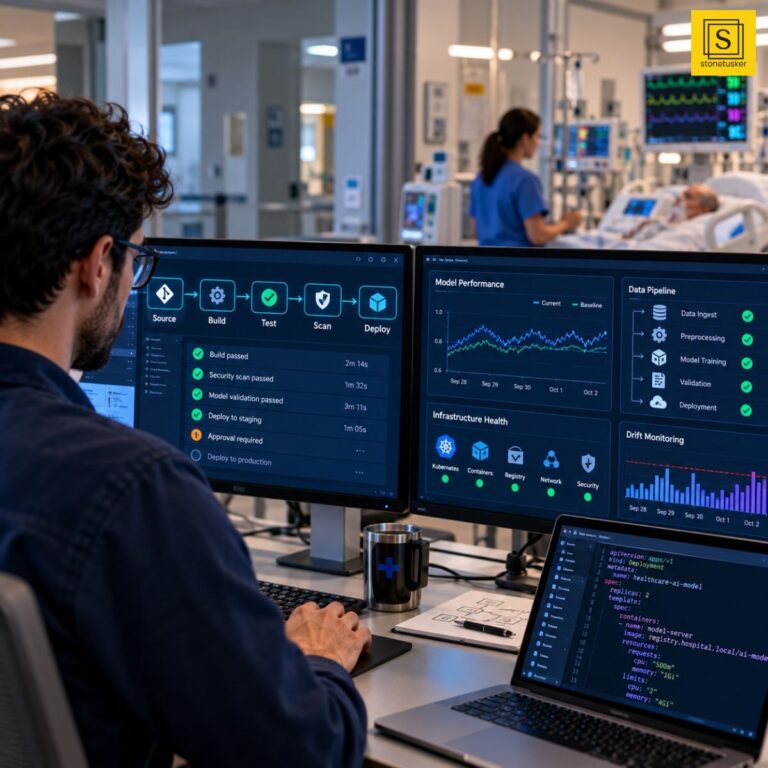
HIPAA Technical Safeguards Mapped to CI/CD Controls
What each standard in 45 CFR 164.312 means for your pipeline, and the evidence an auditor will actually ask to see.
Executive brief
- The HIPAA Security Rule's technical safeguards (45 CFR 164.312) cover five standards: access control, audit controls, integrity, person or entity authentication, and transmission security. A CI/CD pipeline touches all five the moment it builds or deploys software that handles electronic protected health information (ePHI).
- The rule is technology neutral. No CI tool is "HIPAA compliant" by itself, and no regulator certifies one. What you can do is map each standard to a specific pipeline control and keep proof that the control ran.
- The failures we see most often are boring ones: shared service accounts, long-lived deploy keys, unsigned artifacts, and real patient data sitting in test fixtures and build logs.
- "Addressable" does not mean optional. It means you implement the control or document why an equivalent alternative is reasonable.
- The audit-ready goal is one traceable chain: person, commit, review, build, signed artifact, deployment, running system.
What the technical safeguards require
Section 164.312 is short. Five standards, each with a few implementation specifications, and each specification is labeled either required (R) or addressable (A).
| Standard | Implementation specification | Type |
|---|---|---|
| Access control, 164.312(a) | Unique user identification | R |
| Access control | Emergency access procedure | R |
| Access control | Automatic logoff | A |
| Access control | Encryption and decryption | A |
| Audit controls, 164.312(b) | Record and examine activity in systems holding ePHI | R |
| Integrity, 164.312(c) | Mechanism to authenticate ePHI | A |
| Person or entity authentication, 164.312(d) | Verify the identity of whoever seeks access | R |
| Transmission security, 164.312(e) | Integrity controls; encryption in transit | A |
Addressable gets misread constantly. If a specification is addressable, you assess whether it's reasonable and appropriate for your environment. If it is, you implement it. If it isn't, you write down why and put an equivalent measure in place. Skipping it silently is the one option you don't have.
Where a pipeline falls inside HIPAA scope
Here's the question teams skip: is the pipeline itself holding ePHI? Often it shouldn't be. A pipeline that builds code from synthetic data and pushes images into a production cluster doesn't store patient records.
It still matters, a lot. Whoever can change what gets deployed can change how a system that does hold ePHI behaves, including who can read it. So your risk analysis should treat pipeline access as a path to ePHI even when no ePHI flows through it.
The pipeline is directly in scope when any of these are true: integration tests run against a copy of production data, a migration job connects to the live database, logs from a build or deploy step capture request payloads, or a managed CI vendor processes any of the above. In that last case you need a business associate agreement (BAA) with the vendor, and you should ask hard questions about runner isolation before signing.
The mapping: safeguard to pipeline control
This is the table we hand to engineering leads. The right column is what you'll be asked for during an assessment, so build the control and the evidence trail together.
| HIPAA safeguard | CI/CD control | Evidence to keep |
|---|---|---|
| Unique user identification | SSO into the CI platform and source host; no shared accounts; machine identities per pipeline, not per team | IdP user list, service account inventory with owners |
| Emergency access | Documented break-glass deploy path, time-boxed, alerting on use | Break-glass log entries with post-use review notes |
| Automatic logoff | Session timeouts on CI and registry consoles; short-lived tokens; ephemeral runners destroyed after each job | Platform session settings, token TTL config |
| Encryption and decryption | Secrets in a vault or KMS-backed store; encrypted registry and state storage; encrypted runner disks | KMS key policies, storage encryption settings |
| Audit controls | CI, SCM, registry, and cluster audit logs shipped to append-only storage; deploy events tied to commit and approver | Log pipeline config, retention policy, sample queries |
| Integrity | Protected branches, required reviews, signed commits or tags, signed artifacts, provenance, digest-pinned deploys, drift detection | Branch rules, signature verification logs, admission policy |
| Person or entity authentication | MFA for humans (phishing-resistant for approvers); OIDC federation for pipelines instead of stored keys | IdP MFA enforcement report, OIDC trust policies |
| Transmission security | TLS 1.2 or higher everywhere, mTLS between services, TLS-verified registry pulls, no plaintext payloads in logs | Ingress and mesh config, scan results |
Access control and authentication in practice
Unique identity, for people and for pipelines
Unique user identification sounds like a solved problem until you look at the CI platform. There's a deploy-bot account whose token six people know, a shared admin login someone created for a vendor onboarding in 2021, and a personal access token belonging to an engineer who left last spring and still powers a nightly job.
Fix the people side with SSO and SCIM so offboarding is automatic. Fix the machine side with a separate identity per pipeline, owned by a named team, with an expiry review. When a deploy happens, the log should say which pipeline did it and which human approved it. One name each.
Stop storing cloud keys in the CI system
Person or entity authentication applies to machines too. Long-lived cloud access keys sitting in CI variables are the single most common finding we write up. Use OIDC federation so the job proves who it is to the cloud provider and receives credentials that expire in minutes. Nothing to rotate, nothing to leak from a variable dump.
Break-glass, because production does break
The emergency access specification is required, and it's the one teams forget until an outage forces improvisation. Build the path before you need it: a documented procedure, a separate role that's normally empty, time-boxed elevation, a page to security when it's used, and a review within a day or two. An unlogged emergency is just a policy violation with a good excuse.
Audit controls and integrity in practice
Audit logs that survive the incident
The audit controls standard asks you to record and examine activity in systems that contain ePHI. For delivery, that means the CI platform's own audit log (who changed pipeline definitions, secrets, runner settings), source control events (merges, force pushes, permission changes), registry pushes and pulls, and cluster admission or deploy events.
Send them somewhere the people being audited can't edit. Object storage with retention locks works. A SIEM works. A log file on the CI server doesn't.
Examining is the other half of the sentence, and it gets neglected. Write two or three saved queries, such as "any pipeline definition changed outside a reviewed merge" and "any production deploy without a linked approval," and run them on a schedule.
Integrity is about what runs, not just what's stored
The integrity standard is about protecting ePHI from improper alteration or destruction. In delivery terms, the risk is someone altering the software that handles it. Branch protection with required reviews gets you the first link. Signing the artifact at build time, then verifying the signature at admission time in the cluster, gets you the rest: what's running is what was reviewed, and nothing swapped it in between.
Deploy by image digest, never by a mutable tag. Generate an SBOM and build provenance with each release so you can answer "which running services contain this vulnerable library" in minutes rather than days.
Tools we reach for: Sigstore cosign for signing, an admission controller such as Kyverno or OPA Gatekeeper for verification, and an immutable registry setting so tags can't be overwritten.
Transmission security and encryption
Most of this is configuration you already know how to do: TLS 1.2 or higher on every endpoint, mTLS inside the cluster if you run a mesh, certificate verification left on in every client, including the "temporary" internal tool someone built with verification disabled.
The pipeline-specific wrinkles are smaller and easier to miss. Build and deploy logs are a transmission and storage channel too, so a stack trace that echoes a request body can carry PHI into a third-party log service. Add a scrubber, and add a test that fails if a known fake patient identifier appears in captured output.
On encryption at rest: registries, Terraform state (which routinely contains secrets), artifact caches, and runner volumes all deserve a line in your inventory.
Six-step implementation playbook
- Scope the pipeline against ePHI.For each pipeline, record whether it touches ePHI directly, which environments it deploys to, and which vendors process its data. Update the risk analysis with the result.
- Replace shared and long-lived credentials.Move humans to SSO with MFA and machines to OIDC federation. Inventory every service account and assign an owner.
- Gate changes to production.Protect main branches, require at least one reviewer who isn't the author, and block pipeline definition changes that skip review.
- Sign at build, verify at deploy.Sign artifacts and provenance in CI, then enforce verification with an admission policy so unsigned images are rejected.
- Centralize and protect audit logs.Ship CI, SCM, registry, and cluster logs to append-only storage. Save the review queries and schedule them.
- Keep PHI out of tests and logs.Use synthetic or de-identified data in lower environments, add log scrubbing, and put a canary identifier test in the pipeline to catch leaks.
Anti-patterns that fail audits
| Anti-pattern | Safeguard it breaks | Replace it with |
|---|---|---|
Shared deploy-bot token | Unique user identification | Per-pipeline identity with a named owner |
| Cloud keys in CI variables | Entity authentication, encryption | OIDC federation, short-lived credentials |
Deploying :latest | Integrity | Digest-pinned, signature-verified images |
| Production snapshot used in staging tests | Access control, audit controls | Synthetic or de-identified datasets |
| CI logs retained on the CI server only | Audit controls | Append-only, centrally retained logs |
| Admin who approves their own pipeline edits | Integrity, audit controls | Separate reviewer required by branch rules |
| Break-glass role that is always assigned | Emergency access | Empty by default, time-boxed, alerting |
Regulatory notes worth knowing
Three things are worth keeping in view. First, HIPAA requires you to retain required documentation, such as policies, procedures, and risk analyses, for six years (45 CFR 164.316). The rule doesn't set a retention period for audit logs themselves, but many teams align pipeline approval and deployment records to the same six years and confirm the choice with counsel.
Second, NIST SP 800-66 Revision 2 is HHS-referenced guidance for implementing the Security Rule and is a good source for the risk-analysis structure your pipeline mapping should plug into.
Third, in January 2025 HHS published a proposed update to the Security Rule that would, among other changes, make encryption and multi-factor authentication explicit requirements and drop the required versus addressable distinction. Check its current status before you plan around it. Building to the stricter version now costs little, and it's what most security teams would pick anyway.
Primary sources: the HHS Security Rule overview, the text of 45 CFR 164.312, and NIST SP 800-66 Rev. 2. If you also work under medical device or payment rules, the same pipeline controls carry over, with different evidence expectations for IEC 62304, SOC 2, and PCI DSS.
FAQ
Does HIPAA require a specific CI/CD tool or certification?
No. The Security Rule is technology neutral, and HHS doesn't certify tools. A vendor can sign a business associate agreement and offer useful controls, but compliance depends on how you configure and use the system and on your documented risk analysis.
Is a CI/CD pipeline in scope for HIPAA?
It is if it creates, receives, maintains, or transmits ePHI, for example when tests run on real patient records or logs capture PHI. A pipeline that only handles synthetic data usually holds no ePHI, but it deploys into systems that do, so access to it still belongs in your risk analysis.
What's the difference between required and addressable specifications?
Required specifications must be implemented as written. Addressable ones must be implemented if reasonable and appropriate, and if not, you document why and use an equivalent alternative. Addressable never means optional.
Do we have to sign our build artifacts?
The rule doesn't name artifact signing. The integrity standard does require protecting ePHI from improper alteration or destruction, and signing with verification at deploy time is a practical way to show that what runs in production is what you reviewed and built.
How long should we keep pipeline audit logs?
HIPAA doesn't set a retention period for audit logs themselves, but it requires keeping required documentation for six years. Many teams apply six years to pipeline approval and deployment records and confirm that choice with legal counsel.
Can we use hosted CI such as GitHub Actions or GitLab CI?
Yes, as long as you handle the PHI question honestly. The cleanest approach is to keep PHI out of the pipeline entirely. If PHI will flow through a hosted service, you need a business associate agreement and a clear view of how runners are isolated.
Not sure your pipeline would survive a HIPAA assessment?
We map your delivery pipeline to the technical safeguards, close the gaps that matter, and set up the evidence trail so audits stop being a scramble. Tell us what you're running today.
Talk to Stonetusker about your pipeline