DevOps Investment Playbook for Series B Startups: What to Build in the First 90 Days
You just raised your B round. Your team is growing from 15 to 50 engineers. Here's where your DevOps investment should go first, and what to deliberately ignore until later.
Executive Brief
- Series B is the inflection point where ad hoc DevOps stops working. The practices that kept a 10-person team shipping fast (manual deployments, shared staging, informal code review) become bottlenecks when the team triples.
- Your first 90 days of DevOps investment should focus on three things: a reliable CI/CD pipeline that every team uses, a standardized development environment, and basic observability. Everything else can wait.
- Don't hire a full platform team yet. At 30 to 50 engineers, one senior DevOps/platform engineer plus a 90-day consulting engagement produces better results than three junior DevOps hires who'll spend six months figuring out what to build.
- The most expensive DevOps mistake at Series B is over-engineering: adopting Kubernetes when your workload doesn't need it, building an internal developer platform when a well-configured CI/CD pipeline covers 80% of the need, or implementing a service mesh for five microservices.
- SOC 2 Type II is coming (your enterprise customers are already asking for it). Build compliance into your CI/CD from day one so it doesn't become a retrofit project six months from now.
Why Series B Is the Inflection Point
At Series A, your entire engineering team fits in one room. Everyone knows the codebase. Deployments are a Slack message and a script. One person can hold the whole system in their head. This works. It's even fast.
At Series B, you're hiring 3 to 5 engineers per month. By the end of your first year post-raise, you'll have 40 to 60 engineers who have never seen the original codebase. They don't know the deployment process because there isn't a process. They don't know which environment to test on because environments are named after pets and nobody documented which one is stable.
The symptoms show up gradually, then all at once. Deployment failures increase because new engineers don't know the unwritten rules. Staging environments break because two teams deploy to the same one simultaneously. On-call becomes painful because nobody built monitoring when the system was small enough to watch manually. Build times creep up because nobody owns the CI pipeline, and each team adds their own tests without thinking about the total.
The typical Series B timeline: first two months feel fine. Month three, deployment failures spike. Month four, someone breaks production and the incident takes eight hours to resolve because there's no observability. Month five, the VP of Engineering asks "do we need a DevOps person?" The answer was yes, two months ago.
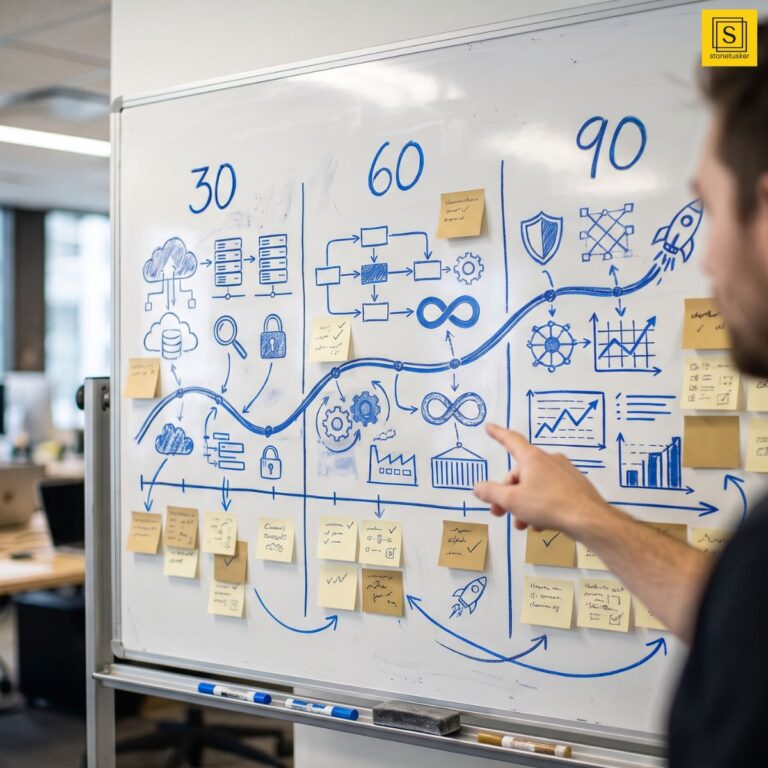
The First 90 Days: What to Build
You don't need to build everything at once. You need to build the three things that unblock your growing team from shipping at the pace your board expects.
Priority 1: A Real CI/CD Pipeline (Days 1 to 30)
If your CI/CD today is a collection of bash scripts, a Makefile, and prayers, this is your first stop. The pipeline you build in month one will be used by every engineer you hire for the next two years, so spend the time to get it right.
What "right" looks like at this stage:
Every pull request triggers a build and automated tests. Tests must pass before merge. There's no way to bypass this. Merges to main trigger an automatic deployment to a staging environment. Deployments to production are one-click (or automatic, if you're bold) with automated rollback if health checks fail.
The specific tooling matters less than you think. GitHub Actions is fine for most startups. GitLab CI is fine. Even Jenkins is fine if someone already knows it, though you'll want to migrate eventually. Pick what your team knows, not what's trending on Hacker News.
What you should NOT do: build a deployment pipeline that requires manual approval from a specific person for every production deploy. That person becomes a bottleneck within a month, and you'll spend the next six months trying to remove them from the process without hurting their feelings.
Priority 2: Environment Standardization (Days 15 to 45)
Every developer needs to run the full application stack locally. Every staging environment needs to match production. These are table stakes, but most Series A companies don't have either one.
For local development: Docker Compose or a similar tool that brings up the entire stack with one command. Include seed data, mock external services, and documentation for common troubleshooting issues. This is the single most impactful thing you can do for new-hire onboarding velocity.
For staging: at minimum, two shared environments. One that's stable (for QA and demos) and one that's current (automatically deployed from main). Name them clearly: "staging-stable" and "staging-canary," not "staging2-backup-new."
If your application is complex enough (multiple services, multiple databases), invest in ephemeral environments that spin up per pull request and tear down on merge. The upfront cost is 2 to 3 weeks of setup time. The ongoing return is that every PR is tested in an isolated, production-like environment without fighting over shared staging.
Priority 3: Basic Observability (Days 30 to 60)
You need three things and you need them in this order: structured logging, application metrics, and alerting.
Structured logging means every log line includes a request ID, a user ID (if applicable), a timestamp, and a severity level, in a format that a log aggregation tool can parse. If your engineers are currently using console.log("something broke"), this is a culture change as much as a tooling change.
Application metrics means tracking the four golden signals for every service: latency, traffic, errors, and saturation. If you're on Kubernetes, Prometheus and Grafana are the default choice. If you're on a simpler infrastructure, Datadog or a similar SaaS tool is faster to set up and worth the monthly cost at this stage.
Alerting means: when something breaks at 2am, the right person gets paged, and they have enough information in the alert to start debugging without opening a laptop and guessing. This requires the logging and metrics to be in place first, which is why it's last in the sequence.
What to Skip Until Series C
This section is more important than the previous one. At Series B, you have limited DevOps bandwidth and a long list of things that seem urgent. Saying no to the wrong things is how you avoid spreading your investment too thin.
| Skip This | Build This Instead | Why |
|---|---|---|
| Kubernetes (unless you're already on it) | ECS/Fargate or managed containers | Kubernetes requires 0.5 to 1 FTE to operate. At 30 engineers, that's too much of your budget spent on infrastructure abstraction. |
| Internal developer platform (IDP) | Well-documented CI/CD golden paths | An IDP makes sense at 100+ engineers. At 30 to 50, good documentation and standardized templates cover 80% of the same need. |
| Service mesh (Istio, Linkerd) | Application-level retries and circuit breakers | Unless you have 20+ microservices, the complexity of a service mesh outweighs the benefits. |
| Custom CLI tooling | Makefile targets and documented scripts | A custom internal CLI takes weeks to build and months to maintain. Makefiles are ugly but universal. |
| Multi-cloud or multi-region | Single-cloud, single-region with automated backups | Multi-cloud adds operational complexity without meaningful business value until you're past $50M ARR. |
This doesn't mean these things are bad. They're good. They're just not right for your current team size, budget, and pace. A $15M Series B should not be spent on infrastructure that a $50M Series C will fund properly.
Staffing: Hire vs. Consult vs. Both
The standard Series B playbook says "hire a head of DevOps." That's the right long-term move. It's the wrong first move.
A senior DevOps/platform hire takes 2 to 4 months to recruit and another 2 to 3 months to ramp up. During those 5 to 7 months, your engineering team is growing fast and your infrastructure debt is compounding. By the time your new hire is productive, the problems they were hired to solve have gotten worse.
The better sequence:
- Month 1: Engage a consulting partner for a 90-day sprint. A team that has done this 30 times can set up your CI/CD pipeline, environment standardization, and basic observability in 90 days. They'll make the architectural decisions that your future DevOps hire will build on, not undo. Look for consultants who'll work alongside your existing engineers, not replace them.
- Month 1 to 3: Start recruiting your first DevOps/platform hire. Run the search in parallel with the consulting engagement. The ideal hire is someone who can own the systems the consultants built and extend them as the team grows. They should start between month 3 and month 5, by which time the foundation is in place.
- Month 6 to 9: Evaluate whether you need a second hire. At 50+ engineers, you may need a two-person platform team. At 30 to 40, one strong hire plus part-time contributions from senior backend engineers is usually sufficient.
The cost of this sequence is roughly the same as hiring two DevOps engineers from day one, but it produces results 3 to 4 months faster because the consulting partner isn't spending their first months learning your business context from scratch; they're applying patterns they've implemented before.
Budget Model for Series B DevOps
Here's what DevOps investment typically looks like for a Series B company growing from 15 to 50 engineers over 12 months:
| Line Item | Annual Cost | Notes |
|---|---|---|
| DevOps/Platform hire (1 FTE) | $150K to $220K | Fully loaded cost. Hire starts month 3 to 5, so Year 1 is partial. |
| Consulting engagement (90 days) | $60K to $150K | Depends on scope and partner. This is a one-time cost. |
| CI/CD tooling (SaaS) | $12K to $36K | GitHub Actions included in GitHub Enterprise. GitLab CI similar. |
| Observability tooling (SaaS) | $24K to $72K | Datadog, New Relic, Grafana Cloud. Scales with infrastructure size. |
| Cloud infrastructure for DevOps | $12K to $30K | Build servers, ephemeral environments, artifact storage. |
| Total Year 1 | $258K to $508K | 3 to 5% of a typical $15M Series B raise |
That's a lot of money in absolute terms. In relative terms, it's 3 to 5% of your raise, invested in the infrastructure that lets the other 95% (product engineering hires, go-to-market spend) operate at full velocity. A team of 50 engineers without DevOps infrastructure will ship at half the rate of a team of 50 with it. You're not spending $400K on DevOps. You're protecting the ROI of the $14M you're spending on everything else.
Building SOC 2 Readiness Early
Your enterprise sales prospects are going to ask for SOC 2 Type II within the next 12 months. If they haven't already, they will as soon as you start closing deals above $100K ACV.
The cheapest time to build SOC 2 compliance into your engineering processes is right now, while you're setting up your CI/CD pipeline anyway. Adding audit-grade deployment logs, RBAC for production access, and automated change management tracking to a new pipeline costs maybe 20% more effort than building the pipeline without them.
Retrofitting SOC 2 compliance into an existing pipeline that wasn't designed for it costs 3 to 6 months of engineering time and usually involves re-architecting the parts you got wrong the first time.
The specific controls to build in from day one:
Deployment audit trail. Every deployment to production is logged with: who triggered it, what changed, which commit SHA, whether tests passed, and whether any manual approvals were involved. This log is immutable (append-only, stored separately from the application logs).
Access controls. No individual SSH access to production. All production changes go through the CI/CD pipeline. Break-glass procedures exist for emergencies, and every break-glass event is logged and reviewed.
Change management. Every production change is associated with a pull request. PRs require at least one reviewer. The reviewer can't be the same person who wrote the code. This is already standard practice at most companies; the difference is documenting it as a policy and having the CI system enforce it.
For a deeper guide on SOC 2 and CI/CD integration, see our SOC 2 certification checklist.
The Five Most Expensive Mistakes
1. Adopting Kubernetes too early. Kubernetes is excellent infrastructure for companies with 10+ microservices, a dedicated platform team, and workloads that benefit from orchestration. At Series B, most companies have 3 to 7 services and no platform team. Running those services on ECS, Cloud Run, or even a few well-configured VMs with autoscaling groups is simpler, cheaper, and lets your team focus on the product instead of on YAML files.
2. Hiring for tools instead of problems. Don't hire "a Terraform expert" or "a Kubernetes admin." Hire someone who has scaled engineering teams from 20 to 80 and knows which problems arise at each stage. The tools change; the problems are consistent across every startup at this scale.
3. Building before measuring. Don't invest in CI/CD optimization until you know your current build times. Don't invest in infrastructure cost reduction until you know where the money goes. Don't build an on-call system until you know your incident frequency and types. Measure first, then invest.
4. Treating DevOps as separate from product engineering. If your DevOps hire sits in a separate team, creates tickets for product engineers, and operates as a service desk, you've created a bottleneck with a salary. DevOps capabilities should be embedded in how every team works, not isolated in a team that other teams depend on for every infrastructure change.
5. Ignoring developer experience. If your CI pipeline takes 30 minutes and developers can't test locally, they'll find workarounds. Those workarounds (deploying to a shared dev server, skipping tests, merging without review) create the exact problems your DevOps investment was supposed to prevent. Fast feedback loops aren't a luxury; they're how you keep engineering discipline at scale.
Frequently Asked Questions
We're at Series A with 10 engineers. Should we start investing in DevOps now?
Should we use a monorepo or multiple repos?
How much of our Series B should go to DevOps vs. product engineering?
Our CTO says we should build our own deployment tooling. Is that right?
When should we bring in a DevOps consulting partner vs. figuring it out ourselves?
What's the risk of waiting too long to invest in DevOps?
If your team just raised Series B and you need DevOps foundations built before your next wave of engineering hires, we've helped over a dozen post-B startups set up CI/CD, observability, and SOC 2 readiness in 90 days.
Talk to us about your 90-day planSubeesh Sivanandan
Founder & CEO, Stonetusker Systems. 26+ years across platform engineering, DevOps, CI/CD, release engineering, and embedded Linux. Subeesh has worked with Series A through Series D startups to build engineering infrastructure that scales with their teams, helping founders avoid the common over-engineering traps that slow down fast-growing companies. Connect on LinkedIn.